Support Vector Machines (SVMs) were first proposed by Vladimir Vapnik and Alexey Chervonenkis in the mid-1960s and have since evolved into one of the most flexible and effective machine learning tools available [1]. At their core, SVMs rest on some genuinely beautiful mathematics, and in this post, we’ll walk through it together in manageable pieces. This post aims to be self-contained: detailed enough that you can learn about the topic in its entirety without juggling multiple resources, yet concise enough so you can avoid the trap of minutiae.
Use the table of contents below to navigate the post:
1 Hard-margin SVM
1.1 Intuition of margin
Consider a training dataset \(\mathcal{D} = \big \{ (x_i, y_i) \big \}_{i=1}^M\), where $x_i \in \mathbb{R}^D$ is the $i$-th feature vector, and $y_i \in \{+1,-1\}$ is its binary label. A hyperplane splits this $D$-dimensional feature space into two half-spaces. If we assume (for now) that our dataset is linearly separable, there are infinitely many valid hyperplanes. We would like to estimate the optimal separating hyperplane that will correctly classify the two classes with the smallest classification error. The SVM prefers a hyperplane that does not favor any particular class. Geometrically, this corresponds to choosing a hyperplane that maximizes the distance between the hyperplane and the closest data points from both classes [2]. Intuitively, a hyperplane that scrapes right past our data is sensitive to small perturbations, while one with a wide buffer zone generalizes better.
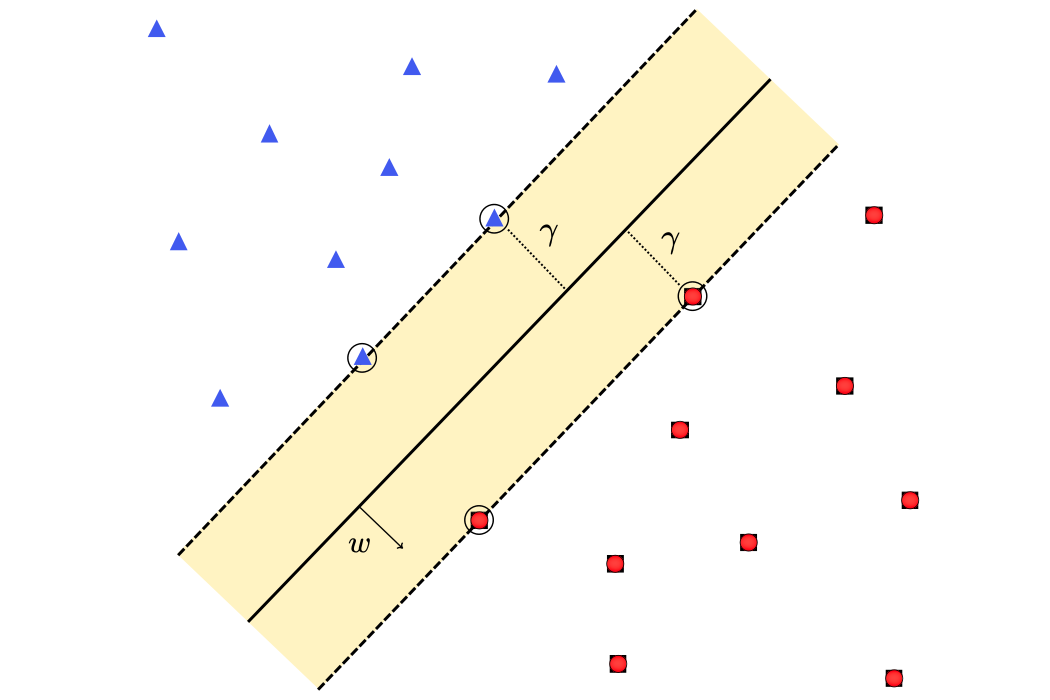
The data points that lie closest to the decision surface (or hyperplane) are called support vectors, and the distance from the hyperplane to the support vectors in either class defines the margin.
1.2 Optimal margin classifier
In a $D$-dimensional space, a hyperplane is defined as follows:
where $w \in \mathbb{R}^D$ is the normal vector orthogonal to the hyperplane, and $b \in \mathbb{R}$ is the bias term. For points lying on the hyperplane, we have
Recall that a hyperplane $h(x)$ divides the original $D$-dimensional space into two half-spaces, such that every point labeled $y_i = +1$ satisfies $h(x_i) > 0$, and every point labeled $y_i = -1$ satisfies $h(x_i) < 0$. As such, the hyperplane $h(x)$ acts as a linear classifier that predicts the label $y$ of a point $x$ according to the following decision rule:
Meanwhile, consider a point $x \in \mathbb{R}^D$ such that it does not lie on the hyperplane. Further let $x_p$ be the projection of $x$ onto the hyperplane along the normal vector $w$. Let $\gamma \gt 0$ be the distance from point $x$ to $x_p$ on the hyperplane.
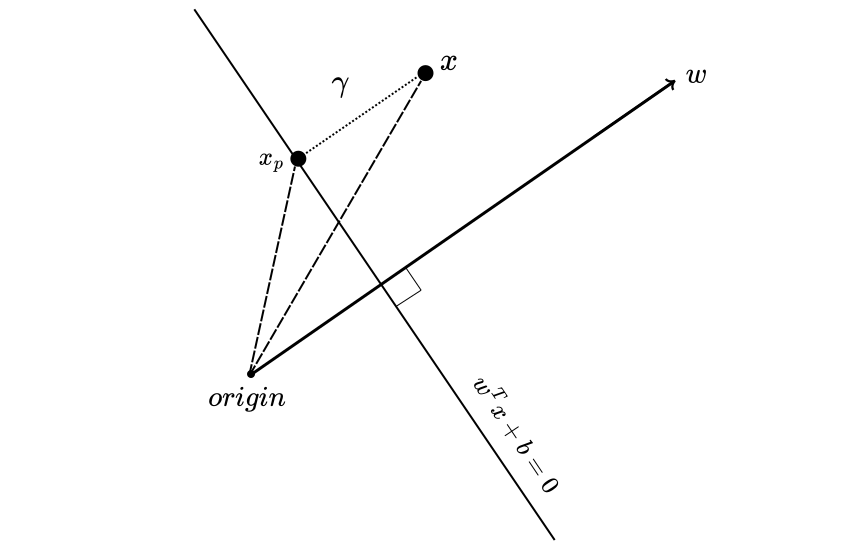
Since $w$ is the normal vector, the distance $\gamma$ is simply a scaling of $w$. Let’s assume that $w$ is of unit length $\lVert w \rVert = 1$, so following vector addition we can write:
Here $\gamma$ gives the directed distance of the point $x$ from $x_p$ in terms of the unit weight vector $\frac{w}{\lVert w \rVert}$. Note that $\gamma$ is positive when it points in the same direction as $w$, and negative when it points in the opposite direction.
Substituting Eq. (4) into the hyperplane Eq. (1) yields
From Eq. (5), we can express the directed distance from the point to the hyperplane as
Since the distance must be nonnegative, we can multiply $\gamma$ by the point’s label $y$, which is $+1$ when $h(x) > 0$ and $-1$ when $h(x)<0$. Thus, the distance of a point $x$ from the hyperplane $h(x)$ is given as
Now, if we choose $x$ to be the point closest to the hyperplane, the distance $\tilde\gamma$ is the margin. We define the smallest distance between the hyperplane and all training points as
Note that scaling $w$ and $b$ in the hyperplane Eq. (2) by the same constant $c>0$ does not change the hyperplane. Hence, we scale $(w, b)$ by the canonical normalization such that
A support vector satisfies $y_i(w^T x_i + b)=1$, while any point that is not a support vector satisfies $y_i(w^T x_i + b) > 1$. The geometric margin is $\gamma^{*} = \frac{1}{\lVert w \rVert}$ and the width of the margin band is $\frac{2}{\lVert w \rVert}$.
With the canonical normalization above, we can pose the following constrained optimization problem:
Maximizing the problem in Eq. (10) is equivalent to minimizing the following problem:
Rather than minimizing the $l_2$-norm in Eq. (11), we often choose to minimize the squared norm because it yields a strictly convex quadratic objective. Thus, the new optimization problem becomes
The SVM formulation in Eq. (12) is known as the primal optimization problem. The duality principle implies that an optimization problem may be viewed from either of two perspectives, the primal problem or the dual problem. In the next section, we will see how to transform the primal problem in Eq. (12) into an equivalent dual optimization problem.
2. Duality of SVM
2.1 Primal and dual problems
2.1.1 Lagrangian
Consider a general optimization problem (the primal problem) defined as
where $x \in \mathbb{R}^N$ is the optimization variable, $f_0(x)$ is the objective function, $f_i(x) \le 0$ are $M$ inequality constraints, and $h_i(x) = 0$ are $P$ equality constraints.
The general idea in Lagrangian duality is to take the problem’s constraints into account by augmenting the objective function with a weighted sum of the constraint functions. We define the Lagrangian associated with the problem in Eq. (13) as
We refer to $\alpha_i$ as the Lagrange multiplier associated with the $i$-th inequality constraint $f_i(x) \le 0$, and $\beta_i$ as the Lagrange multiplier associated with the $i$-th equality constraint $h_i(x) = 0$.
The optimal value of the primal problem, denoted by $p^{*}$, is given by
2.1.2 Lagrange dual function
Given a Lagrangian, we define its Lagrange dual function as
The Lagrange dual function is the pointwise infimum of a family of affine functions of $(\alpha, \beta)$, and thus it is concave even when the original problem in Eq. (13) is nonconvex.
2.1.3 Lagrange dual problem
Given the primal problem in Eq. (13), we define its Lagrange dual problem as
The optimal value of the dual problem, denoted by $d^{*}$, is given by
The dual problem is always a convex optimization problem since the objective to be maximized is concave and the constraint is convex [3]. This is the case whether or not the primal problem in Eq. (13) is convex.
📖 Terminology
Concave maximization over a convex set is convex optimization.
2.2 Weak and strong duality
The optimal value of the Lagrange dual problem $d^{*}$ gives us the best lower bound on the optimal value $p^{*}$ of the primal problem, i.e.,
which holds for both convex and nonconvex problems. This property is called weak duality.
The difference $p^{*} - d^{*}$ is referred to as the optimal duality gap, which is always nonnegative [3]. If the optimal duality gap is zero, then we say that strong duality holds, i.e.,
If strong duality holds, solving the dual is equivalent to solving the primal [4]. However, strong duality does not hold in general, but we usually (but not always) have strong duality if the primal problem is convex, i.e., of the form
where $f_0, \ldots, f_M$ are convex functions. Beyond convexity, the conditions which guarantee strong duality are called constraint qualifications.
📝 Note
Convexity + Constraint Qualifications ⟹ Strong DualityOne simple but well-known constraint qualification is Slater’s condition: there exists an $x \in \operatorname{relint} D$ such that
Such a point is often referred to as strictly feasible, since the inequality constraints hold with strict inequalities. Slater’s theorem states that strong duality holds if Slater’s condition holds and the optimization problem is convex.
Slater’s condition in Eq. (22) can be refined when some of the inequality constraint functions $f_i$ are affine. If the first $K$ constraint functions $f_1, \ldots, f_K$ are affine, then strong duality holds provided the following weaker condition holds: there exists an $x \in \operatorname{relint} D$ with
Detailed proof of the Slater’s theorem can be found in Boyd and Vandenberghe’s Convex Optimization book (see Sec. 5.3.2, pp. 234-236).
2.3 Karush-Kuhn-Tucker (KKT) conditions
For general problems: for an optimization problem with differentiable objective and constraint functions, if strong duality holds, any pair of primal and dual optimal points must satisfy the following KKT conditions:
For convex problems: for a convex optimization problem with differentiable objective and constraint functions, any points that satisfy the KKT conditions are primal and dual optimal, and have zero duality gap, i.e., $p^{*}=d^{*}$.
For convex problems satisfying Slater’s condition: for a convex optimization problem with differentiable objective and constraint functions that satisfies Slater’s condition, the KKT conditions provide necessary and sufficient conditions for optimality.
2.4 SVM dual form
Let’s revisit the primal SVM formulation in Eq. (12), which can be equivalently expressed as the following constrained problem:
where we introduce a constant $\frac{1}{2}$, which does not affect the optimal $w, b$ but simplifies our later derivations. This is a differentiable, convex optimization problem that satisfies Slater’s condition; therefore, strong duality $(p^{*}=d^{*})$ holds, and the KKT conditions are necessary and sufficient for optimality.
We first define the Lagrangian of the primal SVM problem as
Recall that the Lagrange dual function can be formulated as
In order to obtain the extremum of the Lagrangian with respect to $w$ and $b$, we compute the gradient of $\mathcal{L}(w,b,\alpha)$ with respect to $w$ and $b$, and set them to zero,
and we thus have
Similarly,
Plugging Eq. (33) and Eq. (34) into Eq. (31), we get
Hence, the dual problem can be written as
This is a convex quadratic programming (QP) problem that can be efficiently solved with the Sequential Minimal Optimization (SMO) algorithm. Exactly how to solve such a QP problem is beyond the scope of this post. The dual optimization problem is introduced here mainly because it is easy to kernelize.
However, recall that according to the KKT condition in Eq. (27), we have
which gives rise to two scenarios:
- $\alpha_i = 0$, or
- $y_i(w^Tx_i+b) = 1$
This is a very important insight, since if $\alpha_i > 0$, then $y_i(w^Tx_i+b) = 1$, i.e., the training data points $x_i$ whose $\alpha_i$’s are nonzero are the support vectors. Once we have the Lagrange multipliers $\{\alpha_i\}$, we can reconstruct the weight vector $w$ as a linear combination of support vectors
where $\mathcal{S}$ denotes the set of the indices of the support vectors. This “sparse” representation is advantageous for making new predictions since the final classifier depends only on the small subset of data points $x_i$ with $\alpha_i > 0$, i.e., the support vectors.
SVM Classifier: For any new point $z$, we predict the class as
where the $\operatorname{sign}$(·) function returns $+1$ for any positive argument, and $-1$ for any negative argument.
3 Kernels
3.1 Feature maps
Imagine a binary classification problem as shown in Fig. 3(a). Each data sample is represented by a single feature $x \in \mathbb{R}$, and the dataset cannot be separated by a linear hyperplane. How can we extend the linear SVM model to solve such a nonlinear problem?
To make life easier, we can transform each data sample to a higher-dimensional feature space where it is more likely to exhibit linear patterns. In our classification problem, for example, we map each sample from the $1$-dimensional input space into a $2$-dimensional feature space via the feature mapping:
where $\phi$ is a feature map, which maps the original input attributes to the features. As shown in Fig. 3(b), each sample now has two features, and we can find a linearly separable hyperplane in the new feature space.
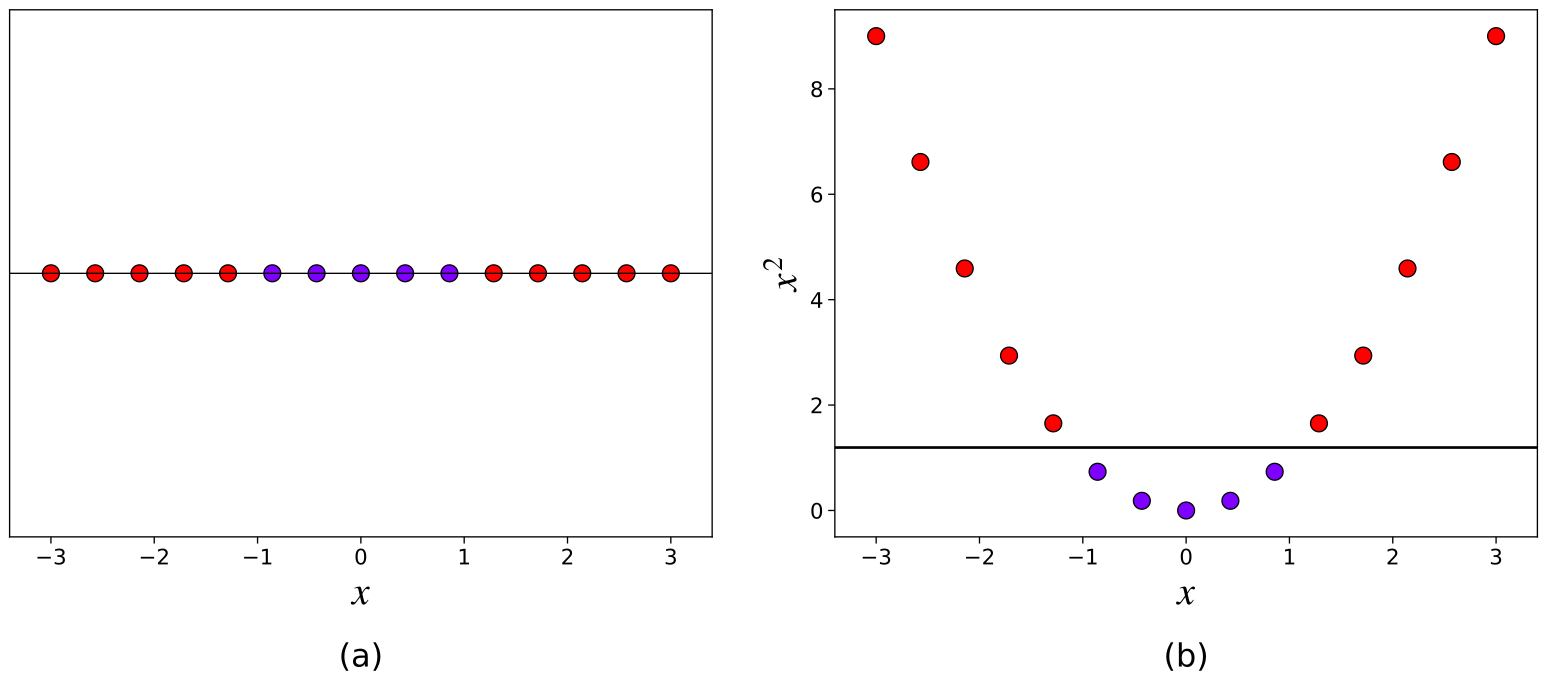
The idea of “lifting” our data into a higher-dimensional space is very cool. However, feature mapping usually causes the number of features to blow up! Explicitly constructing such a mapping is computationally inefficient, especially when the new feature space is very high-dimensional [5]. Fortunately, the kernel trick comes to the rescue.
3.2 Kernel trick
Let’s rewrite the SVM formulation in Eq. (36) by replacing the original input attributes $x$ with a feature map $\phi(x)$:
where $\phi(x_i)^T \phi(x_j)$ is equivalently written as $\langle\phi(x_i), \phi(x_j)\rangle$, emphasizing the inner product of the two feature vectors.
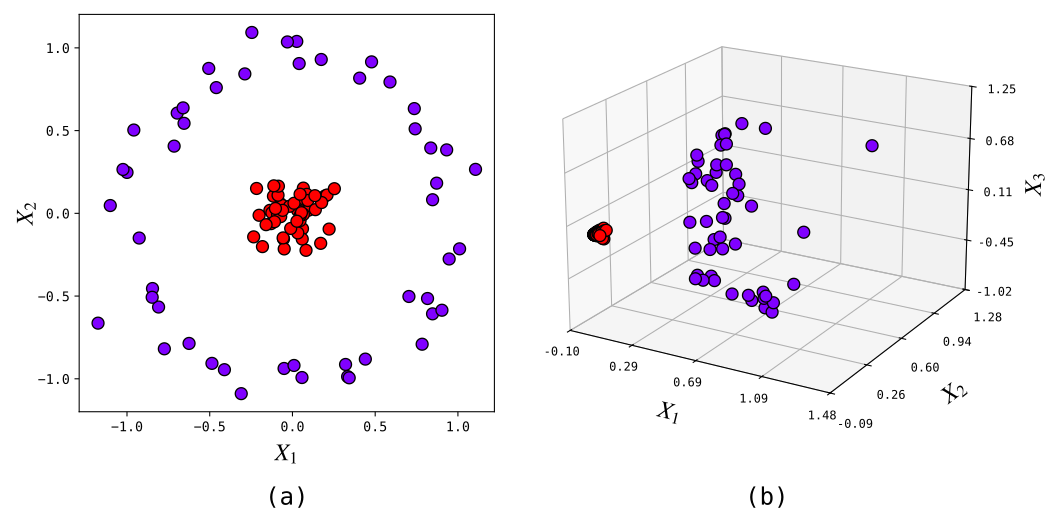
Now let’s look at another classic binary classification problem as shown in Fig. 4(a). We are working with $2$-dimensional data samples that are not linearly separable in the input space. Each data sample is represented by
For a polynomial kernel of degree $2$, the corresponding feature map $\phi$ is given by
The inner product in the feature space is
Now consider a kernel function $k$ in a $2$-dimensional input space defined as follows:
Expanding it gives
Did you notice what just happened? We just demonstrated that through the kernel function $k(x_i,x_j)$ we can implicitly compute the inner product $\langle\phi(x_i), \phi(x_j)\rangle$ directly from the original input space rather than constructing the explicit feature mapping. This is known as the kernel trick. The key advantage of the kernel trick is computational efficiency.
An example would help this make more sense.
Let
and its corresponding inner product in the feature space is
Explicitly constructing both feature vectors and then taking their inner product requires 13 operations (11 multiplications, 2 additions).
Now consider direct kernel evaluation:
Direct kernel evaluation requires only 4 operations (3 multiplications, 1 addition). In other words, a suitable kernel function cheaply computes the inner product $\langle\phi(x_i), \phi(x_j)\rangle$ in the feature space without the lifting.
Let’s formalize the concept of a kernel function. Let $\mathcal{X}$ denote an input space. A function $k:\mathcal{X} \times \mathcal{X} \rightarrow \mathbb{R}$ is a kernel function over $\mathcal{X}$ if there exist a real Hilbert space $\mathcal{H}$ and a feature map $\phi:\mathcal{X} \rightarrow \mathcal{H}$ such that
where $\langle \cdot,\cdot \rangle$ denotes the inner product on $\mathcal{H}$.
But can any function be used as a kernel function? The answer is no. Not every function is a valid kernel. Mercer’s theorem provides the theoretical foundation for characterizing valid kernels (see Michael Jordan’s lecture notes). However, note that Mercer’s theorem only tells us whether a candidate similarity function is admissible for use as a kernel, not how well it would perform [6].
Some common kernels include:
- Linear Kernel: $k(x_i,x_j) = \langle x_i, x_j \rangle = x_i^Tx_j$. This is the simplest kernel. It applies no feature mapping and is equivalent to the standard linear SVM.
- Polynomial Kernel: $k(x_i,x_j) = (\gamma \langle x_i, x_j \rangle + r)^{d}$, where $\gamma \gt 0$ is a scale factor, $r$ is a constant term, and $d$ is the degree of the polynomial. In our example in Eq. (45), the values are $\gamma = 1$, $r = 0$, and $d = 2$.
- Radial Basis Function (RBF) Kernel: $k(x_i,x_j) = \exp (-\gamma {\lVert x_i - x_j \rVert}^2)$, where $\gamma \gt 0$ is a scale factor. The RBF kernel is also called the Gaussian kernel and is a popular default choice for nonlinear problems.
- Sigmoid Kernel: $k(x_i,x_j) = \tanh (\gamma \langle x_i, x_j \rangle + r)$. This kernel is inspired by the activation function used in neural networks.
3.3 The kernelized dual
Now let’s reformulate the dual problem in Eq. (41) by replacing the inner product $\langle\phi(x_i), \phi(x_j)\rangle$ with a kernel function $k(x_i,x_j)$:
This reformulation is what allows SVMs to learn a linear decision boundary in feature space, which corresponds to a nonlinear decision boundary in the original input space.
Classifier: For any new point $z$, the predicted class can be expressed in terms of the kernel:
4 Regularized SVM
4.1 Slack variables
So far, we’ve seen that when a dataset cannot be separated by a hyperplane, we can use kernels to implicitly map the data to a higher-dimensional space. While it generally increases the likelihood that we can find a separating hyperplane in the new feature space, we can’t always guarantee a perfect separation when the dataset contains noise, outliers, or overlapping classes. In such cases, assuming perfect linear separability either makes the problem infeasible or results in a classifier with a very small margin and poor generalization.
This leads to the concept of a soft-margin SVM, which allows some classification errors while maximizing the margin. The soft-margin SVM relaxes the hard-margin constraints by introducing slack variables $\xi_i \ge 0$, which allow some training examples to fall within the margin region or even be misclassified. However, we also want to minimize the sum of the slack variables $\sum_{i} \xi_i$ to keep the number of such misclassified examples as small as possible. Thus, we reformulate our optimization problem as follows:
The value of $\xi_i$ indicates the degree of violation of the margin $\left(\frac{1}{\lVert w \rVert}\right)$ for each data point $i$:
- $\xi_i=0$: The point is correctly classified and outside or exactly on the margin.
- $0<\xi_i <1$: The point is on the correct side of the decision boundary but within the margin. It is still correctly classified but considered a margin violation.
- $\xi_i \geq 1$: The point is on the wrong side of the decision boundary.
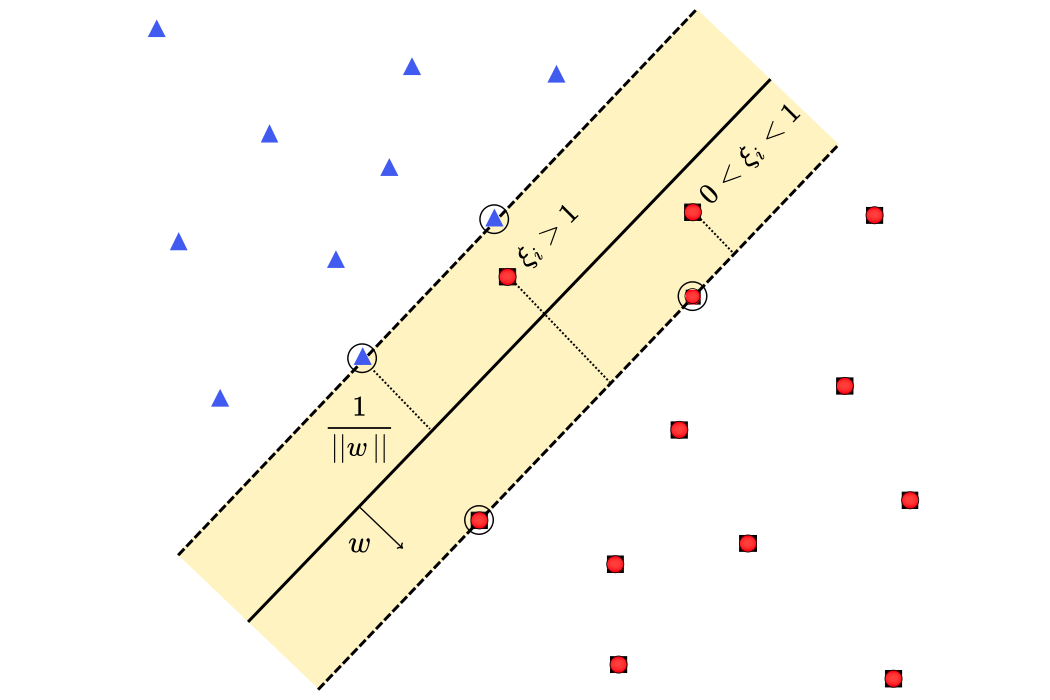
The sum of the slack variables $\sum_{i} \xi_i$ measures the total margin violation across data points, and the regularization parameter $C \gt 0$ controls the trade-off between maximizing the margin and minimizing classification errors. Here’s how $C$ affects the margin and misclassifications:
- Small C: Large margin, more misclassifications (risk of underfitting).
- Large C: Small margin, fewer misclassifications (risk of overfitting).
4.2 Loss-function form
The primal soft-margin problem in Eq. (53) can be reformulated with the hinge loss as an unconstrained optimization problem. The constraint in Eq. (54) of our soft-margin formulation can be written more concisely as
Since we also require $\xi_i\geq0$, the minimum value that satisfies both constraints is
This expression is precisely the hinge loss. Substituting this expression into the objective of our soft-margin formulation yields an unconstrained formulation that combines the $l_2$-regularizer and the hinge loss:
The first term in the new formulation is called the regularization term (or regularizer), and the second term is called the error term (or loss term). The regularizer keeps the weights small and well-behaved, which leads to a larger margin, whereas the loss term penalizes incorrect predictions and margin violations across the training set. The regularization parameter $C$ determines the trade-off between these two terms, balancing margin maximization against hinge-loss minimization.
4.3 Subgradient descent method
Before we continue, let’s reformulate the objective function in Eq. (58) in two steps:
- First, we’ll divide the hinge loss by the total number of training samples $M$.
- We’ll then multiply the overall objective by a scaling factor $\lambda>0$, where $\lambda$ and $C$ are inversely related to each other.
Therefore, the new objective function is given by
The new regularization parameter $\lambda$ makes it more natural to vary the strength of regularization while keeping the objective the same.
In our objective function, both the regularizer and the hinge loss are convex with respect to model parameters $(w,b)$. Furthermore, for $\lambda>0$, the regularizer is strictly convex in $w$, which guarantees that the optimal weight vector $w^*$ is unique. Since a nonnegative sum of convex functions is convex [7], the overall SVM objective is also convex.
In general, we apply the standard gradient descent method to compute the global minimizer of an unconstrained differentiable convex objective. Since the hinge loss function in our SVM objective is nondifferentiable, we use subgradients instead of gradients. The resulting variant of the gradient descent method is called the subgradient descent method, which applies directly to nondifferentiable convex functions [8].
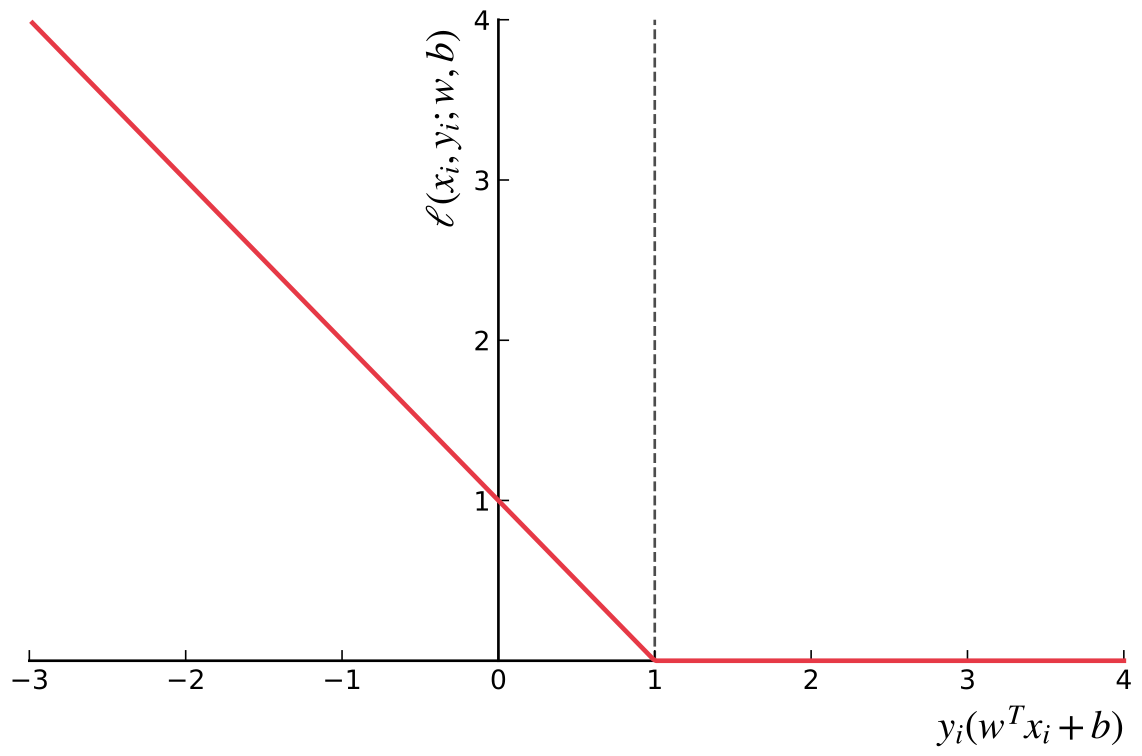
Recall that the hinge loss function is defined as
At the point where $y_i(w^Tx_i+b)=1$, the hinge loss is nondifferentiable (the “kink”), so there is no unique gradient. However, the subgradient at this point can be either the gradient when $y_i(w^Tx_i+b) > 1$ or the gradient when $y_i(w^Tx_i+b) < 1$ or any value in between. The subgradient of the hinge loss with respect to model parameter $w$ is given by
and the subgradient with respect to $b$ is given by
Therefore, the subgradient of the cost function with respect to $w$ is given by
and the subgradient with respect to $b$ is given by
For each iteration $t$, the subgradient descent update rule for minimizing the cost function $J(w,b)$ is defined as
where $0<\eta<1$ is the learning rate.
We are now ready to apply stochastic subgradient descent to optimize the primal soft-margin objective. Check out the notebook for implementation:
5 Closing thoughts
SVMs are a vast topic, and if some of the concepts take a few readings to sink in, that’s okay. Nobody absorbs all the details in one read.
If this all makes sense, you should now have a pretty good mental model of how SVMs work intuitively, and the mathematics behind them should feel less like a pile of formulas to memorize and more like a series of choices you might have made yourself.
If you found this post helpful, consider sharing it with someone who might benefit from it!
If you like this type of content and want to learn more or spot any errors in the post, make sure to reach out to me on X or LinkedIn.
That’s all for now, thanks for reading!